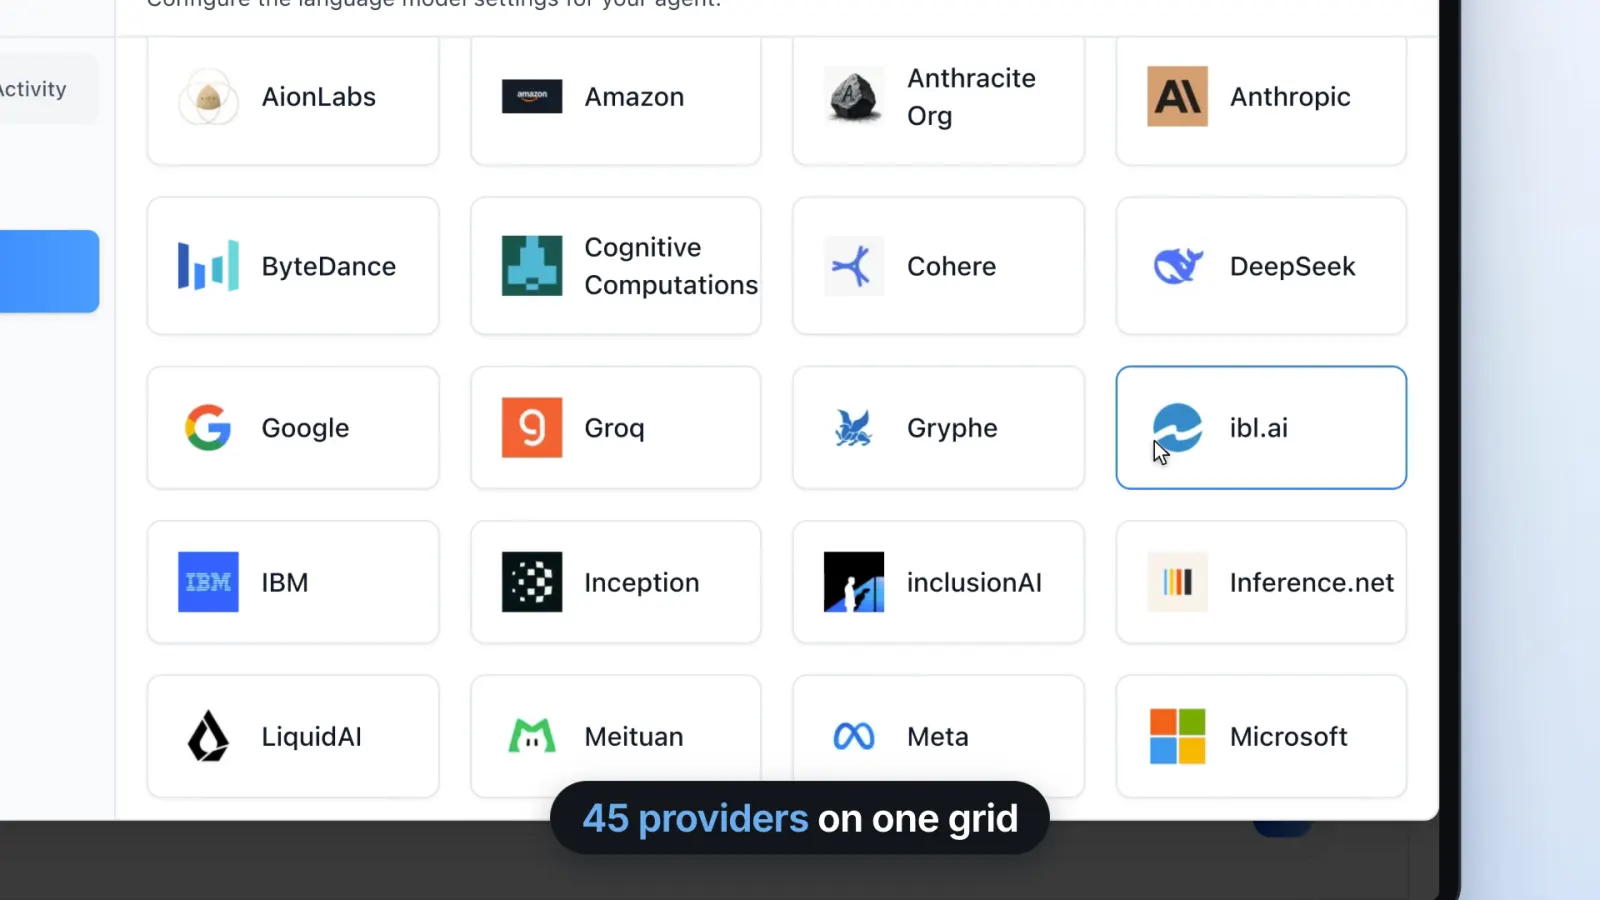
Every agent on ibl.ai picks its model from one grid of 45 providers and 316 chat models, switches to another in one click with its prompts, data and connectors untouched, and reads a catalogue that syncs itself every six hours behind a verification gate; the calls route through gateways that prefer your own keys, because on ibl.ai you own all the code and the data.
The 52-second clip above was recorded on the Lakeview University demo organization on November 6, 2026.
It opens the LLM tab of one agent on Agentic OS, walks the provider grid, switches the agent to GPT-5.2, turns on in-chat model change, and ends on the cost argument in the buyer's own terms.
How many LLM providers can an ibl.ai agent choose from?
On the organization in the video, the LLM tab lists 45 providers and 316 chat models, counted through the platform's own model endpoint on the day of recording.
The grid runs from AionLabs, Amazon and Anthropic through Cohere, DeepSeek, Google, Groq, IBM, Meta, Microsoft, Mistral, NVIDIA, OpenAI and Perplexity to Qwen, Tencent, xAI, Xiaomi and Z.ai, with Amazon Bedrock and Azure OpenAI as hosted routes.
The list is served by the platform, so what an organization sees depends on its own configuration. The docs for the panel are at LLM Configuration and LLM Selection.
How does the model catalogue stay current without a redeploy?
The catalogue syncs itself.
Since the September 18, 2026 platform release (DM 4.379.0), a task runs every six hours, reads each gateway's model list and registers new models under the company that authored them, so a model released this week appears without a hand-edited file and without a redeploy.
Nothing goes live on trust. A discovered model stays inactive until a verification gate has tested five things: multi-turn recall, streaming, tool calling, image input and a real, non-zero cost. A model that fails stays hidden, with the reason recorded.
Hosted catalogues follow the same rule. Since the October 30, 2026 release, Amazon Bedrock and Google Vertex Model Garden sync daily (03:30 and 03:50 UTC), priced at the author's list price and kept off until verified.
A model whose last gateway route is retired is deprecated automatically.
| Source | Sync cadence | Goes live when | Shipped |
|---|---|---|---|
| Gateway model lists (OpenRouter and each provider's own API) | Every 6 hours | Verification gate passes: recall, streaming, tool calling, image input, non-zero cost | 2026-09-18 (4.379.0) |
| Amazon Bedrock | Daily, 03:30 UTC | Priced at list, off until verified | 2026-10-30 |
| Google Vertex Model Garden | Daily, 03:50 UTC | Priced at list, off until verified | 2026-10-30 |
| Any gateway, your keys | On request | Routes to the highest-priority gateway that can serve the model and has a usable key, per-organization keys first | 2026-10-02 (4.412.0) |
What happens to an agent when you switch its model?
Nothing else changes.
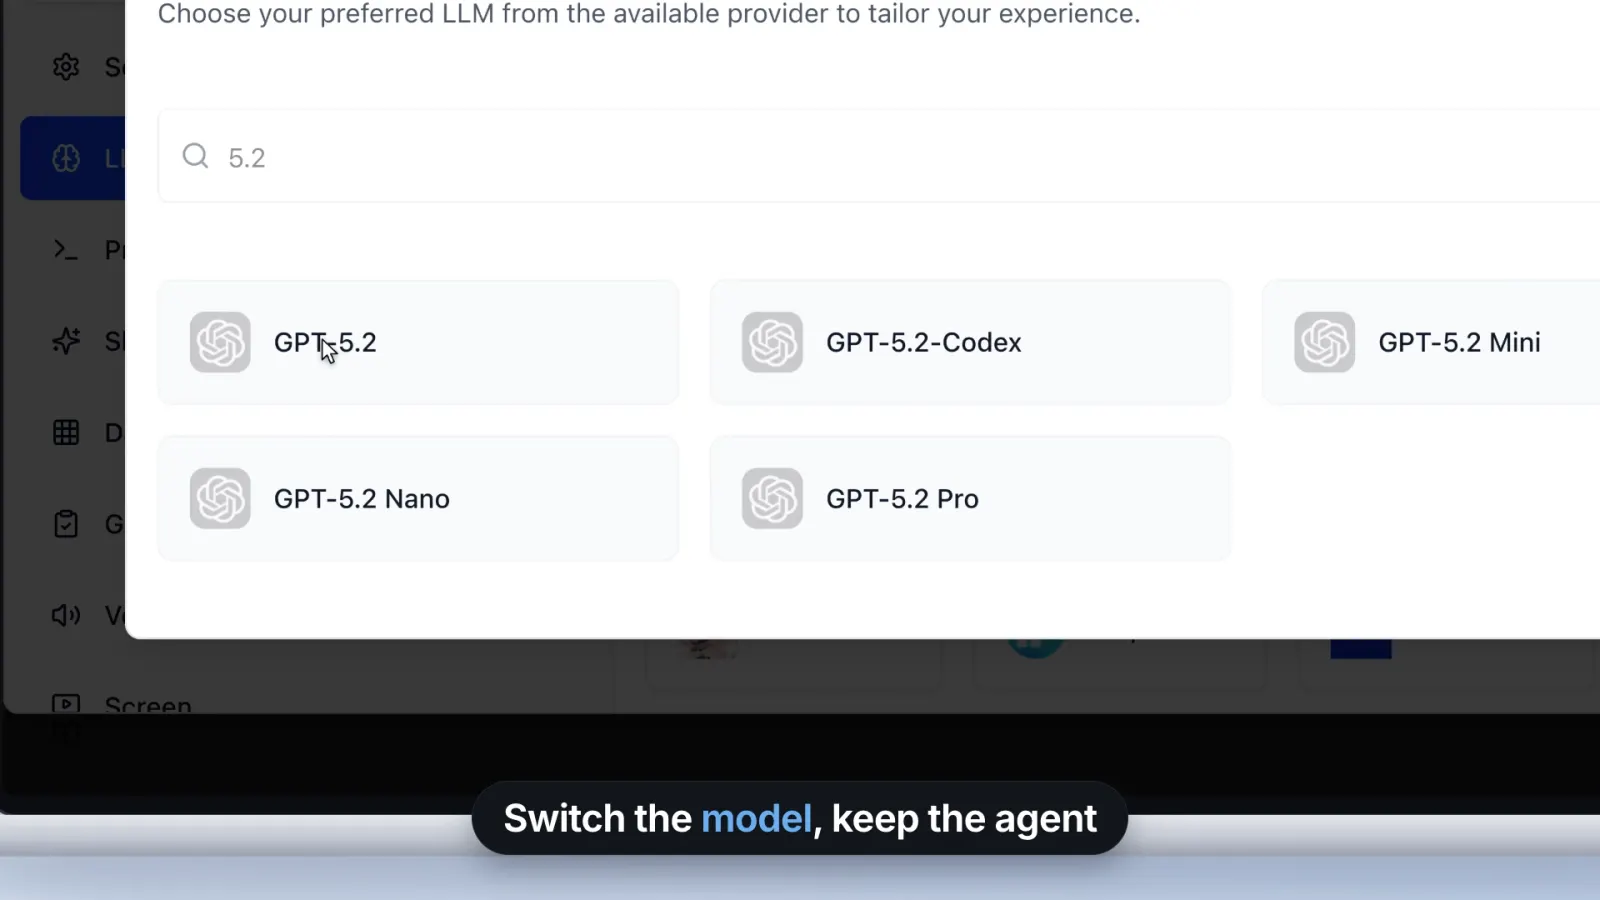
In the video the agent runs on ibl.ai Pro. A click on the OpenAI card opens the LLM Selection dialog, and typing 5.2 in Search leaves five cards: GPT-5.2, GPT-5.2-Codex, GPT-5.2 Mini, GPT-5.2 Nano and GPT-5.2 Pro.
Clicking GPT-5.2 saves the choice immediately, with the toast "LLM updated successfully".
Every subsequent reply comes from the new model. The system prompt, the datasets, the MCP connectors, the skills, the memory and the guardrails all stay exactly as they were, because on ibl.ai the model is a setting on the agent, not the agent itself.
The switch back is one more click.
Can each user pick their own model in a chat?
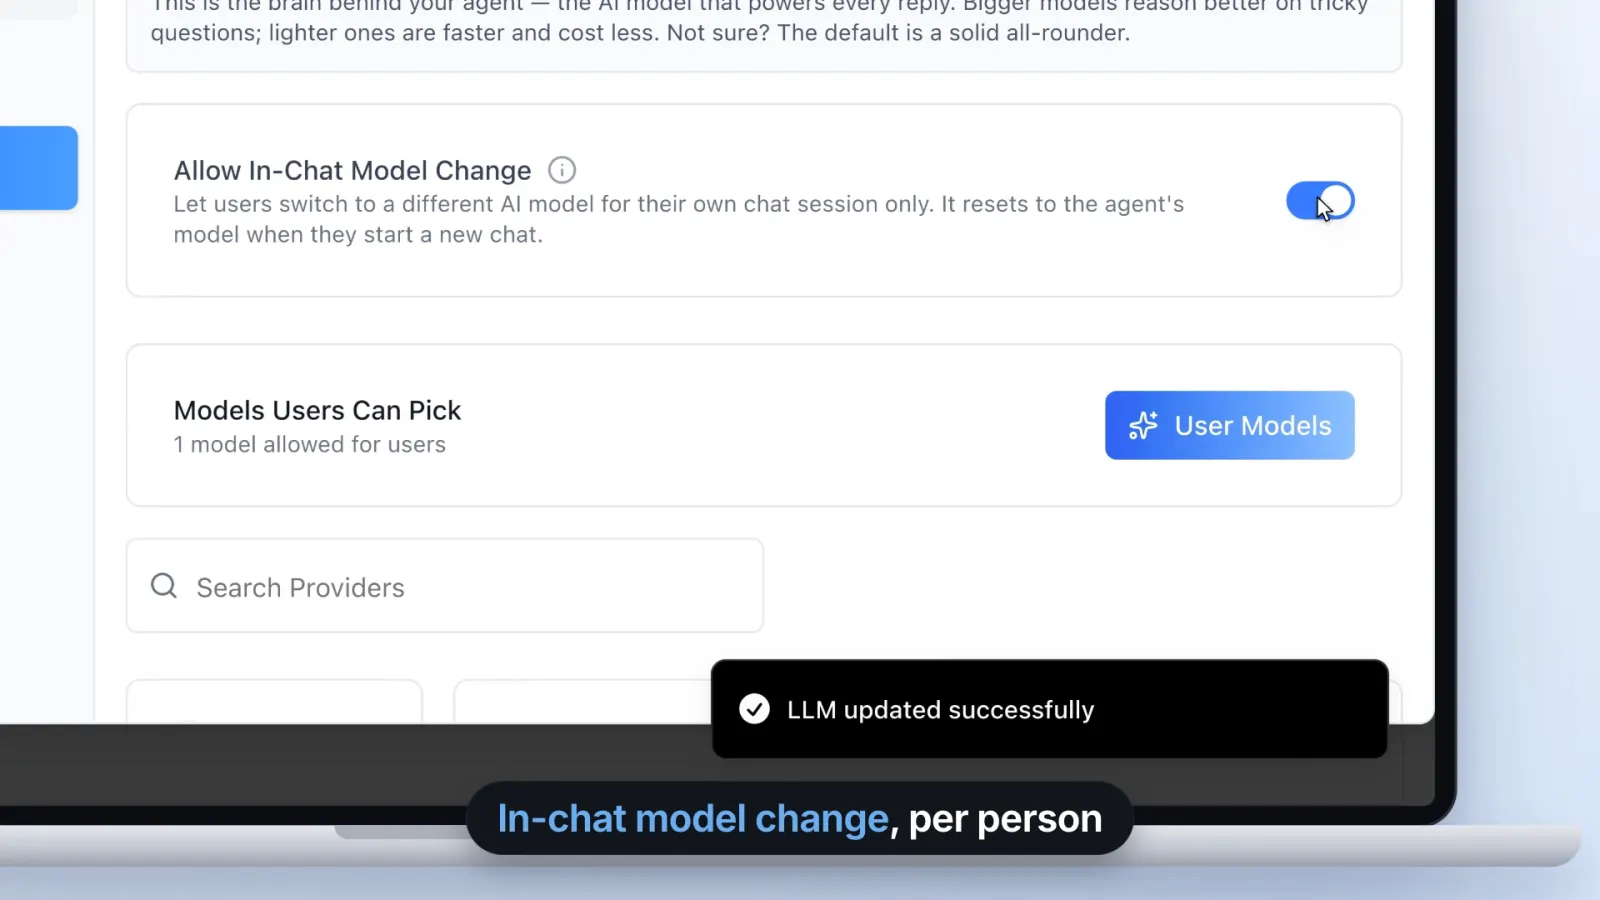
Yes, when the agent allows it. The LLM tab carries an Allow In-Chat Model Change switch: "Let users switch to a different AI model for their own chat session only. It resets to the agent's model when they start a new chat."
Turning it on reveals Models Users Can Pick, where the administrator sets the list a person may choose from (the video shows one model allowed). A person's choice applies to their own chat session and nobody else's, and a new chat starts back on the agent's model.
That pairs with the per-user LLM spend caps that shipped on October 30: a person can pick a heavier model for a hard question, and the organization still decides how much any one person can spend.
Why does a model-agnostic catalogue change what AI costs?
Because below the frontier, models are commodities.
Any model a few months behind the frontier is interchangeable with the next one, and a catalogue of 316 of them on one grid means the price you pay is the usage rate of whichever model is good enough, not the list price of the one vendor you signed with.
Per-seat AI is the wrong shape for that market: a seat bills the same whether a person asked three questions or three hundred, at roughly $30 to $60 per user per month across the enterprise copilots, and it multiplies by headcount regardless of use.
Usage-based pricing on ibl.ai bills the tokens actually consumed, and spend caps hold the ceiling at the organization, agent and user level.
The arithmetic is on the pricing page, and the longer argument is in 69 releases in a week, and why model switching compounds.
Where do the model calls run, and whose keys do they use?
Every endpoint that serves a model is a gateway: OpenRouter, Vertex, Foundry, Bedrock and each provider's own API, unified in the October 2, 2026 release (DM 4.412.0).
A request routes to the highest-priority gateway that can serve the model and has a usable key, with the organization's own keys preferred over platform keys.
So a deployment with provider keys and no ibl.ai key works with no extra configuration, and an air-gapped deployment points the same grid at models served inside the perimeter.
The catalogue, the keys, the routing rules and the agents sit in your own database on infrastructure you run, in your cloud, on-premise or air-gapped, and with ibl.ai you own all the code and the data.